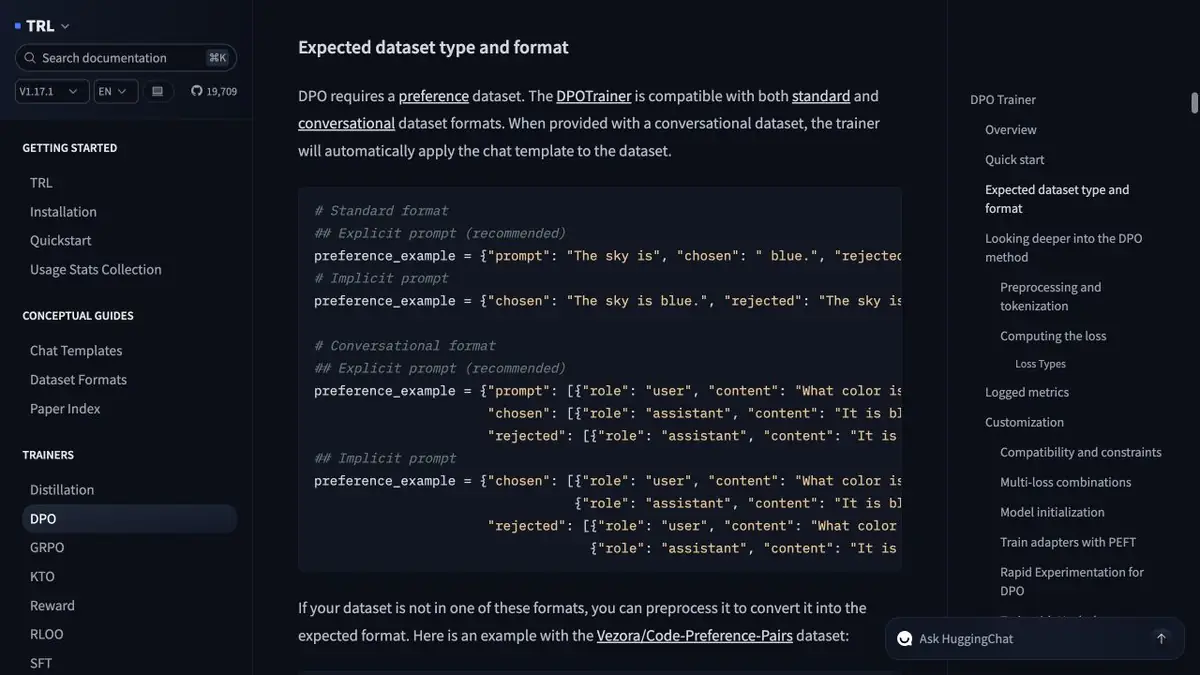
For a DPO, a single request is given a preferred and less successful answer. TRL provides a ready-made class of instruction and describes supported formats.
How to spot a couple of answers
Consider a sample assistant for an internal reference guide. When asked to move a deadline, one response states the rule accurately and another invents an exception. For DPO, save the prompt and both responses, marking the accurate one as preferred. If the second response is both longer and less accurate, the model may associate preference with length. Add pairs that use similar wording but differ in factual accuracy so that the intended criterion is visible in the data.
What to say in TRL
DPOTrainer accepts a dataset with prompt, chosen, and rejected fields. Conversational examples support message roles. Check that both responses answer the same question and contain no information absent from the request or reference guide. Then hold out questions from a different section of the guide for evaluation. Include a pair in which the preferred response asks for clarification.
Control after training
Separately check the exact answers, relevant clarifications and confident fictions. The overall score may improve due to the shorter style, even if some of the old correct answers are missing. Save a few examples next to the run parameters. Check if the dialogue pattern matches during training and testing. Comparison with the original model makes sense on one set of questions, with the same context and the same generation settings. For important scenarios, supplement the automatic metrics with manual content checking.
Suitable tasks
- Test the training on a couple of answers
- Compare before and after DPO
Strengths
- There is a ready-made DPOTrainer class and example formats
- The library is connected to the Transformers ecosystem
Limitations
- Preferences in the dataset affect the resulting behavior
- Evaluation outside the training set needs separate annotations
Selection and conditions
- Free access
- Yes
- Trial period
- Not confirmed
- No sign-up required
- Not confirmed
- Russian interface
- Not confirmed
- Local installation
- Yes
- API
- Not confirmed
“Not confirmed” means there is not enough information. The feature may still be available; check the developer’s terms.
- Input formats
- Text, Data
- Result
- Data, Model
Terms
The open-source library has no pricing plan of its own. Compute, hosting, and the base model's terms of use are separate considerations. Preferences in the dataset affect the resulting behavior.From task to first result
Practical example
- Task
- Test the training on a couple of answers
- What to prepare
- A training set of requests and answers, a compatible model and individual verification examples.
Task brief or prompt
Prepare a short training run. Save the model parameters and compare its answers before and after training on the same verification requests.
Expected result
Quality change report and customized adapter or control point.
How to check the result
- Remove copies and close options between samples.
- Note the content errors and format deviations separately.
An editorial teaching example of a task brief, not the result of hands-on testing of the service. Check that the required mode is available, that you have rights to the source material and that the intended use of the result is permitted.
Check details
Official sources
This description is based on the developer’s material. Features, prices and availability may change; check the primary source before use.